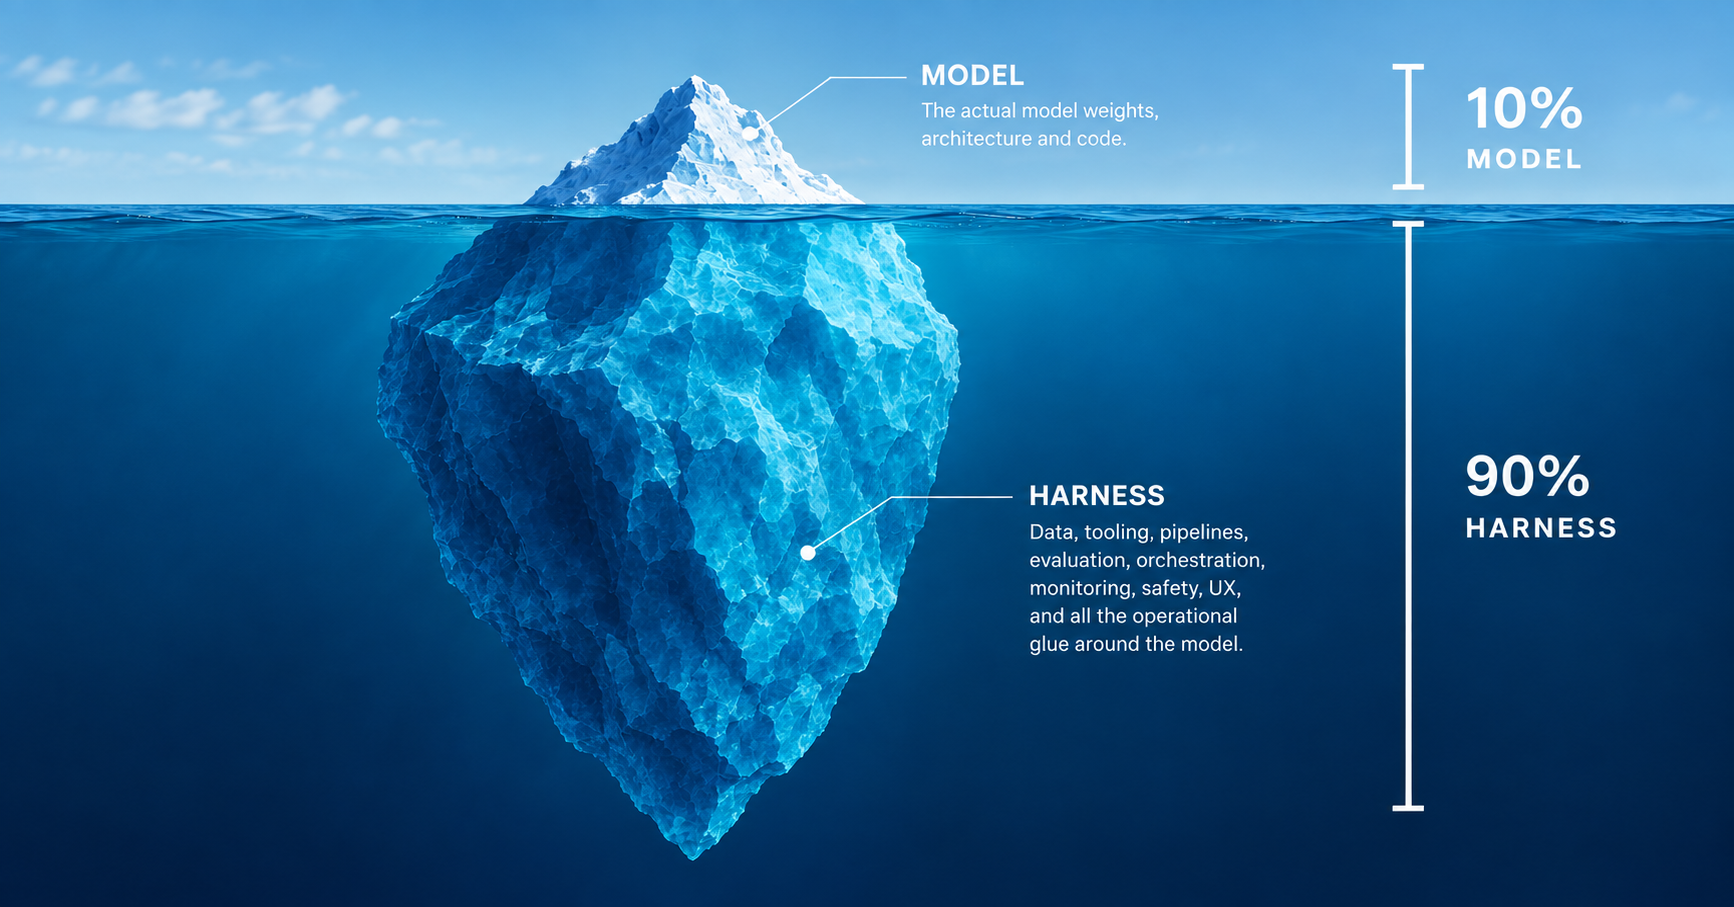
I ran five different coding agents at the same local model, on the same task, with the same frozen test suite — and then I counted why they failed. The answer wasn’t subtle. About 90% of the failures were harness problems. Only about 10% were the model. And here’s the part that should change how you spend your next dollar: throwing a bigger, less-quantized model at it fixed none of them.
I’ve been beating this drum for a while — the tooling is the new model, a good harness beats a bigger brain, AI agents are a context-management strategy in a trenchcoat. Those posts made the claim. This one is me finally doing the boring engineering thing and pinning down the receipts. I promised you a meaner test where correctness isn’t pegged at the ceiling. Here it is.
The Setup
Five terminal agents — hax (C), pi (TypeScript), omp (Rust/TS), kit (Go), and erg, my own unpublished agent in Go — each told to write a PNG decoder in Go that passes a frozen 32-case anchor suite the agent never gets to see. Every one drove the identical model: qwen3-coder-next, an 80B MoE coder model, quantized to Q4, served locally through Ollama. Same weights, same sampling, same server, same prompt, same skills loaded. Ten rounds each.
The only free variable was the harness. So when they failed differently — and they did, wildly — it wasn’t the brain. It was the rig around the brain.
But before the harness carnage, I owe you one setup question: why did all five agents drive that model — two quantizations of a single qwen — instead of the bigger, fancier options on the shelf?
Why Two Flavors of the Same Qwen?
Fair question, because I didn’t start there. I ran the bench against the whole zoo first — gpt-oss-120b (OpenAI’s open reasoning model, on Ollama Cloud), GLM-4.5-Air (Zhipu’s 110B hybrid-reasoning model), devstral, and claude-sonnet-5 as a sanity ceiling. That’s where I learned the first lesson, and it’s why the controlled study ended up on two quantizations of one qwen instead of a leaderboard.
The reasoning models couldn’t drive the loop. gpt-oss is reasoning-first — it buries its work in reasoning_content and mostly never emits a tool call the agent can act on, so it just stalls out with no binary. GLM-4.5-Air has the same hybrid-reasoning shape and the same trouble. devstral is a perfectly capable coder model, but it’s tuned for a specific harness (OpenHands); pointed at these agents it produced essentially nothing, quitting in a few seconds. I dug into the ugliest reasoning-model failure — correct code, but the model refuses to stop — over in Right, But It Wouldn’t Stop.
The lesson: raw capability is not the same as “drives this harness.” A model that puts its work where the harness can’t see it produces nothing — not bad code, no code. claude-sonnet-5 and qwen3-coder-next are the two that behaved like tool-calling coders and actually ran the loops. So for a clean, apples-to-apples correctness comparison I anchored on qwen and held everything constant except quantization: Q4 and Q8, same weights. Which sets up the obvious question — does the higher-fidelity one write better code?
The Code Was Almost Always Right. The Finishing Wasn’t.
Here’s the thing that reframes the whole game. On the three reliable agents, correctness sat at ~0.97–0.98 median. The model wrote good code almost every time. What separated a “finished” run from a failure was almost never the code — it was whether the agent could land the plane.
- hax wrote a correct binary in all 10 rounds — and only finished 4 of them. The other six slammed into a hard-coded 100-turn cap and exited with an error, throwing correct, tested work straight in the trash.
- kit declared itself done after 3 turns, printed “Now let me create the test file:” — and then quit before writing the tests or the Makefile. No binary. Nobody checked.
- pi went bimodal: one run finished a correct binary but couldn’t stop, burning 679 turns and 85M tokens into the wall-clock cap. Another quit after 8 turns with nothing.
None of that is a model problem. That’s the harness declaring victory (or defeat) at the wrong moment — “correct, but won’t stop” is just one cousin in a whole ugly family.
The One That Should Scare You: The False Pass
This is the finding I can’t stop thinking about.
One agent, erg — which stings a little, because erg is mine, an agent I wrote and haven’t even published yet — completed a run cleanly. Its own make test passed. Green across the board. And the binary failed every single malformed-input case — it accepted bad CRCs, missing IEND chunks, truncated files, zero-byte garbage. It rejected nothing.
Why did its tests pass? Because it had followed the “write thorough tests” advice beautifully. Twenty-five test functions. A hundred-plus mentions of invalid/malformed/reject. Nineteen explicit valid=false expectations. All green.
Its tests encoded the exact same wrong reading of the spec as its code did. The tests and the code shared one blind spot, so they agreed with each other perfectly. This is spec-gaming, and it’s not a bug you can fix by telling the model to “test more.”
Think about that for a minute. An agent that has convinced itself it’s correct cannot catch its own blind spot with its own tests. By construction. The only thing that catches this is an independent check against the spec — a reviewer that reads the requirements and the code separately, or a held-out oracle the agent never sees. Self-verification against your own understanding is a mirror, not a test.
A Bigger Model Did Not Help
Short answer: no. Q8 is the less-quantized, higher-fidelity build of the same weights — 1.7x the memory and latency — and it bought me nothing.
No consistent correctness gain. Two agents got worse. And — this is the point — Q8 reproduced the exact same failure modes: hax still exited with a correct binary in the trash, kit still quit early with no binary. The bottleneck was never model fidelity. Paying for the bigger model bought me a bigger memory bill and the identical bugs. (If you’re weighing local hardware for other reasons, I still think buying the metal is a smart hedge — just not this problem’s fix.)
And No, the Skills Didn’t Save It
Every failing run had the shared skills loaded — including ones that literally say “validate inputs, fail loudly, run build and test before finishing.” erg followed the testing skill thoroughly and still gamed itself green.
That’s the sober lesson for the skills-maximalists (I am one). Generic, advice-style skills have a ceiling. They restate good intentions the model already fails to execute under pressure. The leverage isn’t in more careful prose. It’s in mechanism — the harness enforcing the loop — and in ground truth the agent can’t talk its way around.
So What Actually Works
If ~90% of your failures live in the harness, that’s where you spend. In rough order of bang-for-buck:
- An environment-grounded done-gate. Before the agent is allowed to finish, the harness — not the model — runs
make build && make testand checks the deliverables exist. Fails or missing artifacts? Reject “done,” inject the error, force another turn. This one fix alone kills the most common failure in the whole study. The correct solution was usually one nudge away; nobody nudged. - An independent reviewer against the spec. Not the author’s own tests. This is the only thing that catches the false pass.
- Graceful finalization and loop guards. Hit the budget? Commit best-effort and exit clean. Don’t throw away a correct binary because you hit turn 100. And detect no-progress loops so a runaway can’t eat 85M tokens.
Notice what’s not on that list: a bigger model.
Conclusion
Same brain, five bodies, one frozen judge. The brain was fine — better than fine, ~0.97 correct. Nearly every failure that mattered was the body: stopping at the wrong moment, trusting the model’s own “done,” grading its own homework with a marking key it wrote itself. A fancier brain fixed none of it, because none of it was a thinking problem.
The industry already knows this in its bones — on SWE-bench, improving the agent scaffold moved scores more than swapping models. I just watched it happen on a box in my office, controlled down to the sampling seed. The model is a component. The harness is the system. Spend accordingly.
Usual caveats, because honesty beats a clean story: this is one task family, N=10 on Q4, partial N on Q8. The exact numbers are illustrative — the failure modes are the real finding, and those are general. Reproduce before you cite.
If you’re building harnesses, or you think I’ve mis-counted that 90/10 split and want to tell me why, drop me a note on LinkedIn. I’d rather be corrected on a desktop benchmark now than at org scale later.